GaussianTalker: Real-Time High-Fidelity Talking Head Synthesis with Audio-Driven 3D Gaussian Splatting
Kyusun Cho*, Joungbin Lee*, Heeji Yoon*, Yeobin Hong, Jaehoon Ko, Sangjun Ahn, Seungryong Kim
ACM Multimedia 2024
Abstract
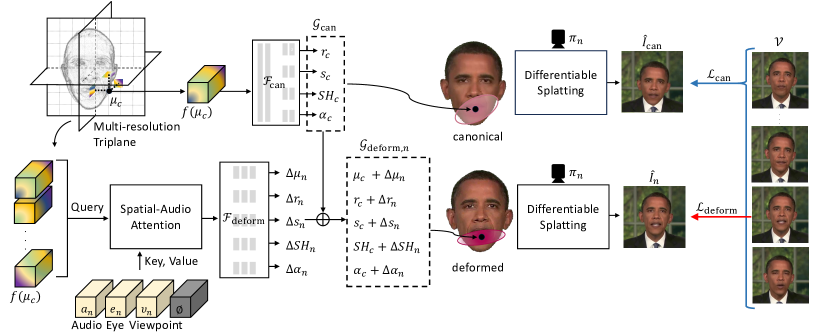
We propose GaussianTalker, a novel framework for real-time generation of pose-controllable talking heads. It leverages the fast rendering capabilities of 3D Gaussian Splatting (3DGS) while addressing the challenges of directly controlling 3DGS with speech audio. GaussianTalker constructs a canonical 3DGS representation of the head and deforms it in sync with the audio. A key insight is to encode the 3D Gaussian attributes into a shared implicit feature representation, where it is merged with audio features to manipulate each Gaussian attribute. This design exploits the spatial-aware features and enforces interactions between neighboring points. The feature embeddings are then fed to a spatial-audio attention module, which predicts frame-wise offsets for the attributes of each Gaussian. It is more stable than previous concatenation or multiplication approaches for manipulating the numerous Gaussians and their intricate parameters. Experimental results showcase GaussianTalker’s superiority in facial fidelity, lip synchronization accuracy, and rendering speed compared to previous methods. Specifically, GaussianTalker achieves a remarkable rendering speed up to 120 FPS, surpassing previous benchmarks.
Project Page Paper Code Live Demo
Live Demo
The whole pipeline — speech synthesis, audio features, Gaussian deformation and splat rendering — runs in your browser, on WebGPU or the CPU. Type a sentence and press Speak; drag the head to turn it. It also runs on its own page.